
Wednesday, November 11, 2026
Deploying a Content Delivery Network (CDN) to distribute your site's assets across fast, globally distributed edge servers closer to users can be a major upgrade for any growing site: it lowers visitor latency and shields your origin server (the backend source of truth holding your original content) from heavy traffic.
Sounds perfect, right? Well... the transition phase can be a bit weird.
We sometimes hear from site owners that right after putting their site behind a CDN, crawler traffic to their server spikes almost immediately, which is exactly what they were trying to fix. Before those edge servers populate their caches, both user visits and crawler requests still need to be fetched directly from the origin.
When moving to a CDN, it's useful to review both how crawl budget works and how to reduce Google's crawl rate in emergencies. This blog post aims to walk you through what to expect with such a move and some of the challenges involved. It's also why we suited up (with hardhat and firehose) to walk you through navigating the transition in Episode 5 of The Non-Canonical Cabinet. If you ever moved to a CDN and wondered about all the new traffic, or if you want to avoid accidentally knocking your site out of Search, this is for you!
So why is everything crawling everywhere all at once?
When you switch over to the CDN, that surge in crawler traffic may happen because of how Google's crawling infrastructure calculates your site's crawl capacity limit (also known as hostload):
- Slower and slower responses decrease crawl rate. Google's automated crawling infrastructure continuously monitors the health and responsiveness of your host server. When response times increase, our crawlers slow down so we don't overwhelm your server and to avoid degrading user experience on your site.
- Fast and stable responses speed up crawling. When a server responds quickly and consistently, our systems interpret that speed as a sign of healthy, capable infrastructure. Provided there is crawl demand, the crawl capacity limit gradually goes up.
The moment your DNS points to a fast CDN edge network, connection times and response times drop dramatically. To our crawling systems, it looks like your server just got a massive hardware upgrade, so our crawlers start ramping up their request rate to match.
The problem. Cache miss on the edge servers it is.
A higher crawl rate wouldn't be an issue if the CDN absorbed all of those requests at the edge. The catch is that a brand-new CDN starts with an empty (cold) cache.
On the very first request for a URL at an edge location, the CDN doesn't have a copy of that asset (HTML documents, CSS, JavaScript, images, and so on) yet; it's a cache miss. To fulfill the request, the edge server has to "walk" all the way back to your origin server, fetch the response, store a cacheable copy for itself, and then serve the client. Only subsequent requests for that same cached URL become cache hits served directly from the edge without bothering your origin. (In our video, the edge server was represented by a rubber chicken running back and forth to a stack of sticky notes. Networking diagrams are subjective.)
Basically, the real bottleneck during a CDN launch is still the origin server.
Human visitors usually cluster around a relatively small set of popular pages (your homepage, top articles, or active promotions) which warm up in the CDN cache quickly. Crawlers do the exact opposite. Their job is to systematically explore the breadth of your URL inventory.
Now combine those two behaviors:
- Fast edge responses signal to Google's crawlers that it's safe to crawl faster.
- As crawlers work through those large numbers of URLs for the first time, every uncached URL triggers a cache miss that passes straight through to your origin server.
Crawlers don't ramp up their crawl rate immediately, and many CDNs include built-in connection pacing that helps smooth out traffic spikes. Even so, until your edge caches are populated (warmed up), your CDN isn't acting as a shield yet, your origin server is still doing the heavy lifting.
You shall not crawl! When blanket bot protection goes too far
Seeing an unexpected surge of automated requests in origin logs right after a migration can understandably make admins nervous, if it's unclear to them why this is happening. It's tempting to look at spiking request graphs when the cache is warming up, and to try to address this by logging into the CDN dashboard and turning on blanket bot protection. To quote Cherry, "BOTS SHALL NOT PASS"!
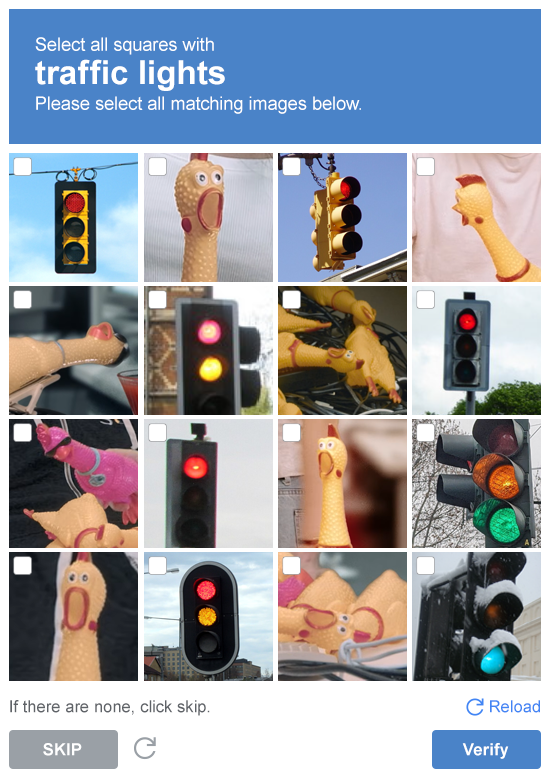
The problem with blanket security rules is right there in the name: without exemptions, they treat all automated traffic the same, including the traffic from crawlers that you care about. When a CDN or Web Application Firewall (WAF) flags automated requests and intercepts them with a challenge like CAPTCHA, Google's crawlers fail the test. (Googlebot has many talents; spotting traffic lights and chickens is not one of them. In fact even Gary cannot solve them sometimes.)
Leaving blanket bot protection enabled without exempting verified crawlers leaves crawlers basically stuck on an error page that's not useful for Search, or other products relying on crawled data. From our perspective, your website appears deliberately restricted or broken. If left in place, our crawlers will back off, and your pages, shopping listings, and your chicken pictures will begin to drop out of Search.
How to train your CDN (without scorching your origin)
You don't need to employ a fire marshal to deploy a CDN; you need the right expectations, and a game plan, such as:
- If you need to block bots, allow verified bots in your CDN and firewall settings. Most major CDNs and WAFs offer a built-in toggle or managed rule to allow known / verified bots, letting your preferred crawlers bypass CAPTCHA challenges while still filtering unwanted traffic (you can identify our crawlers via Google's published IP ranges). Or better yet, configure your robots.txt file or use rules to target specific unwanted bots rather than blocking all automated clients.
- Pre-warm your caches before opening the floodgates. Before routing all traffic through the new CDN, programmatically fetch your highest-traffic, upcoming peak-traffic pages (such as promotional or seasonal launches), and most frequently crawled URLs through the CDN at a controlled pace so edge caches are ready to serve traffic. Or, if unlike Gary you actually have friends, ask them to access two distinct URLs each; that works too.
-
Use
429or503if you need a temporary brake. If crawl volume is still putting critical load on your origin while caches warm up, configure your server or CDN rate-limiting rules to return a429 (Too Many Requests)or503 (Service Unavailable)HTTP status code for a short window (a few hours, or 1-2 days at most) as documented in our guide to urgently reducing the Google crawl rate.
TL;DR Recap (Who Puts a TL;DR at the End?!)
Before you wrap an ethernet cable around the server cabinet and call it a day, remember three things when moving to a CDN:
- Faster responses mean faster crawling: Low CDN edge latency signals to Google's crawlers that your site is healthy and can handle a higher crawl rate.
- Caches only shield you on the second visit: On a cold cache, the first request for every unique URL is a cache miss that goes straight to your origin server. Pre-warm your caches where you can.
-
If necessary, exempt verified crawlers from bot challenges: Don't let blanket
WAF or CAPTCHA rules block Google's crawlers with
403walls or challenge pages; use verified-bot exemptions, and lean on temporary429or503responses if your origin genuinely needs a breather.
Are you not entertained? Watch the Episode!
Watch the Season 1 finale (Episode 5) of The Non-Canonical Cabinet! We explain network architecture using a plastic construction hardhat, a smoking filing cabinet, and a rubber chicken standing in as an edge server, none of which, we're fairly certain, were in our original job descriptions.
Interested in the full Season 1? We attempted to break URLs and robots.txt. We yapped about
404s
and redirects.
Watch all 5 episodes.
We guarantee poultry overload.
Got a weird edge case you want us to pull from the (slightly toasted) cabinet next season (budget pending)? Leave a comment on the video.
Keep your caches warm, your firewalls tidy, and your rubber chickens bubble-wrapped!