Machine learning (ML) code can be compiled on an ML-domain-specific MLIR (Multi-Level Intermediate Representation) compiler. MLIR is an open-source compilation infrastructure geared toward heterogeneous computing platforms. The name multi-level intermediate representation reflects the system's ability to model computations at various abstraction levels and progressively lower them toward machine code.
Rather than acting as a single standalone compiler for a fixed instruction set, MLIR provides a modular framework for representing, optimizing, and lowering machine learning workloads across multiple levels of abstraction.
Originally created at Google and contributed to the LLVM project, MLIR addresses software fragmentation in AI/ML and modern hardware accelerators by connecting high-level ML frameworks (such as JAX, PyTorch, and LiteRT) to specialized hardware targets like Coral NPU through a unified compilation pipeline.
MLIR is widely used across technology stacks to unify machine learning frameworks with heterogeneous silicon:
- Machine learning pipelines: Powering infrastructure in LiteRT (TensorFlow Lite), PyTorch (torch-mlir), JAX, and others.
- Next-gen hardware support: Transforming high-level code to run on highly customized hardware accelerators: GPUs, TPUs, NPUs, and FPGAs.
IREE (Intermediate Representation Execution Environment) is an MLIR-based end-to-end compiler and runtime that lowers ML models to a unified IR. An IREE compiler performs a sequence of passes that lower a high-level representation to an IR expressed using dialects that can be customized to represent target-specific operations.
IREE compilers incorporate important components such as:
- Linalg, TOSA, and LLVM-IR dialects
- Optimization algorithms such as tiling
- The LLVM compiler itself which compiles part of a graph targeting the ML accelerator or the host CPU
LLVM is a set of compiler and toolchain technologies that can be used to develop a frontend for any programming language and a backend for any instruction set. MLIR is part of the LLVM ecosystem.
LLVM is designed around a language-independent intermediate representation (IR) which serves as a portable, high-level assembly language that can be optimized with a variety of transformations over multiple passes. The name LLVM originally stood for Low Level Virtual Machine, but is now an orphan initialism.
MLIR in the Coral software stack
In the Coral NPU toolchain, MLIR works alongside IREE (Intermediate Representation Execution Environment) and LLVM to provide an end-to-end compilation and runtime stack:
- Multi-framework model ingestion: Models exported from JAX (via StableHLO), LiteRT (via TOSA), and PyTorch (via torch-mlir) enter a shared MLIR pipeline without requiring framework-specific hardware backends.
- Heterogeneous execution: MLIR dialects in IREE (flow, stream, and HAL) partition the computation graph across the host CPU and the Coral NPU accelerator, managing buffer allocation and synchronization automatically.
- Standards-based RISC-V code generation: High-level tensor operations lower through linalg and vector dialects into LLVM IR, targeting Coral NPU's 32-bit RISC-V scalar (RV32IMF) and vector (RVV) execution units as well as optional matrix extensions.
Compilation workflow
IREE compilers require plugins for specific target hardware, for example a RISC-V processor such as Coral NPU. ML software developers can initially treat the compiler as a black box, but may eventually want to write customizations to optimize their ML kernels. See the IREE GitHub repository and IREE developer site for information about IREE.
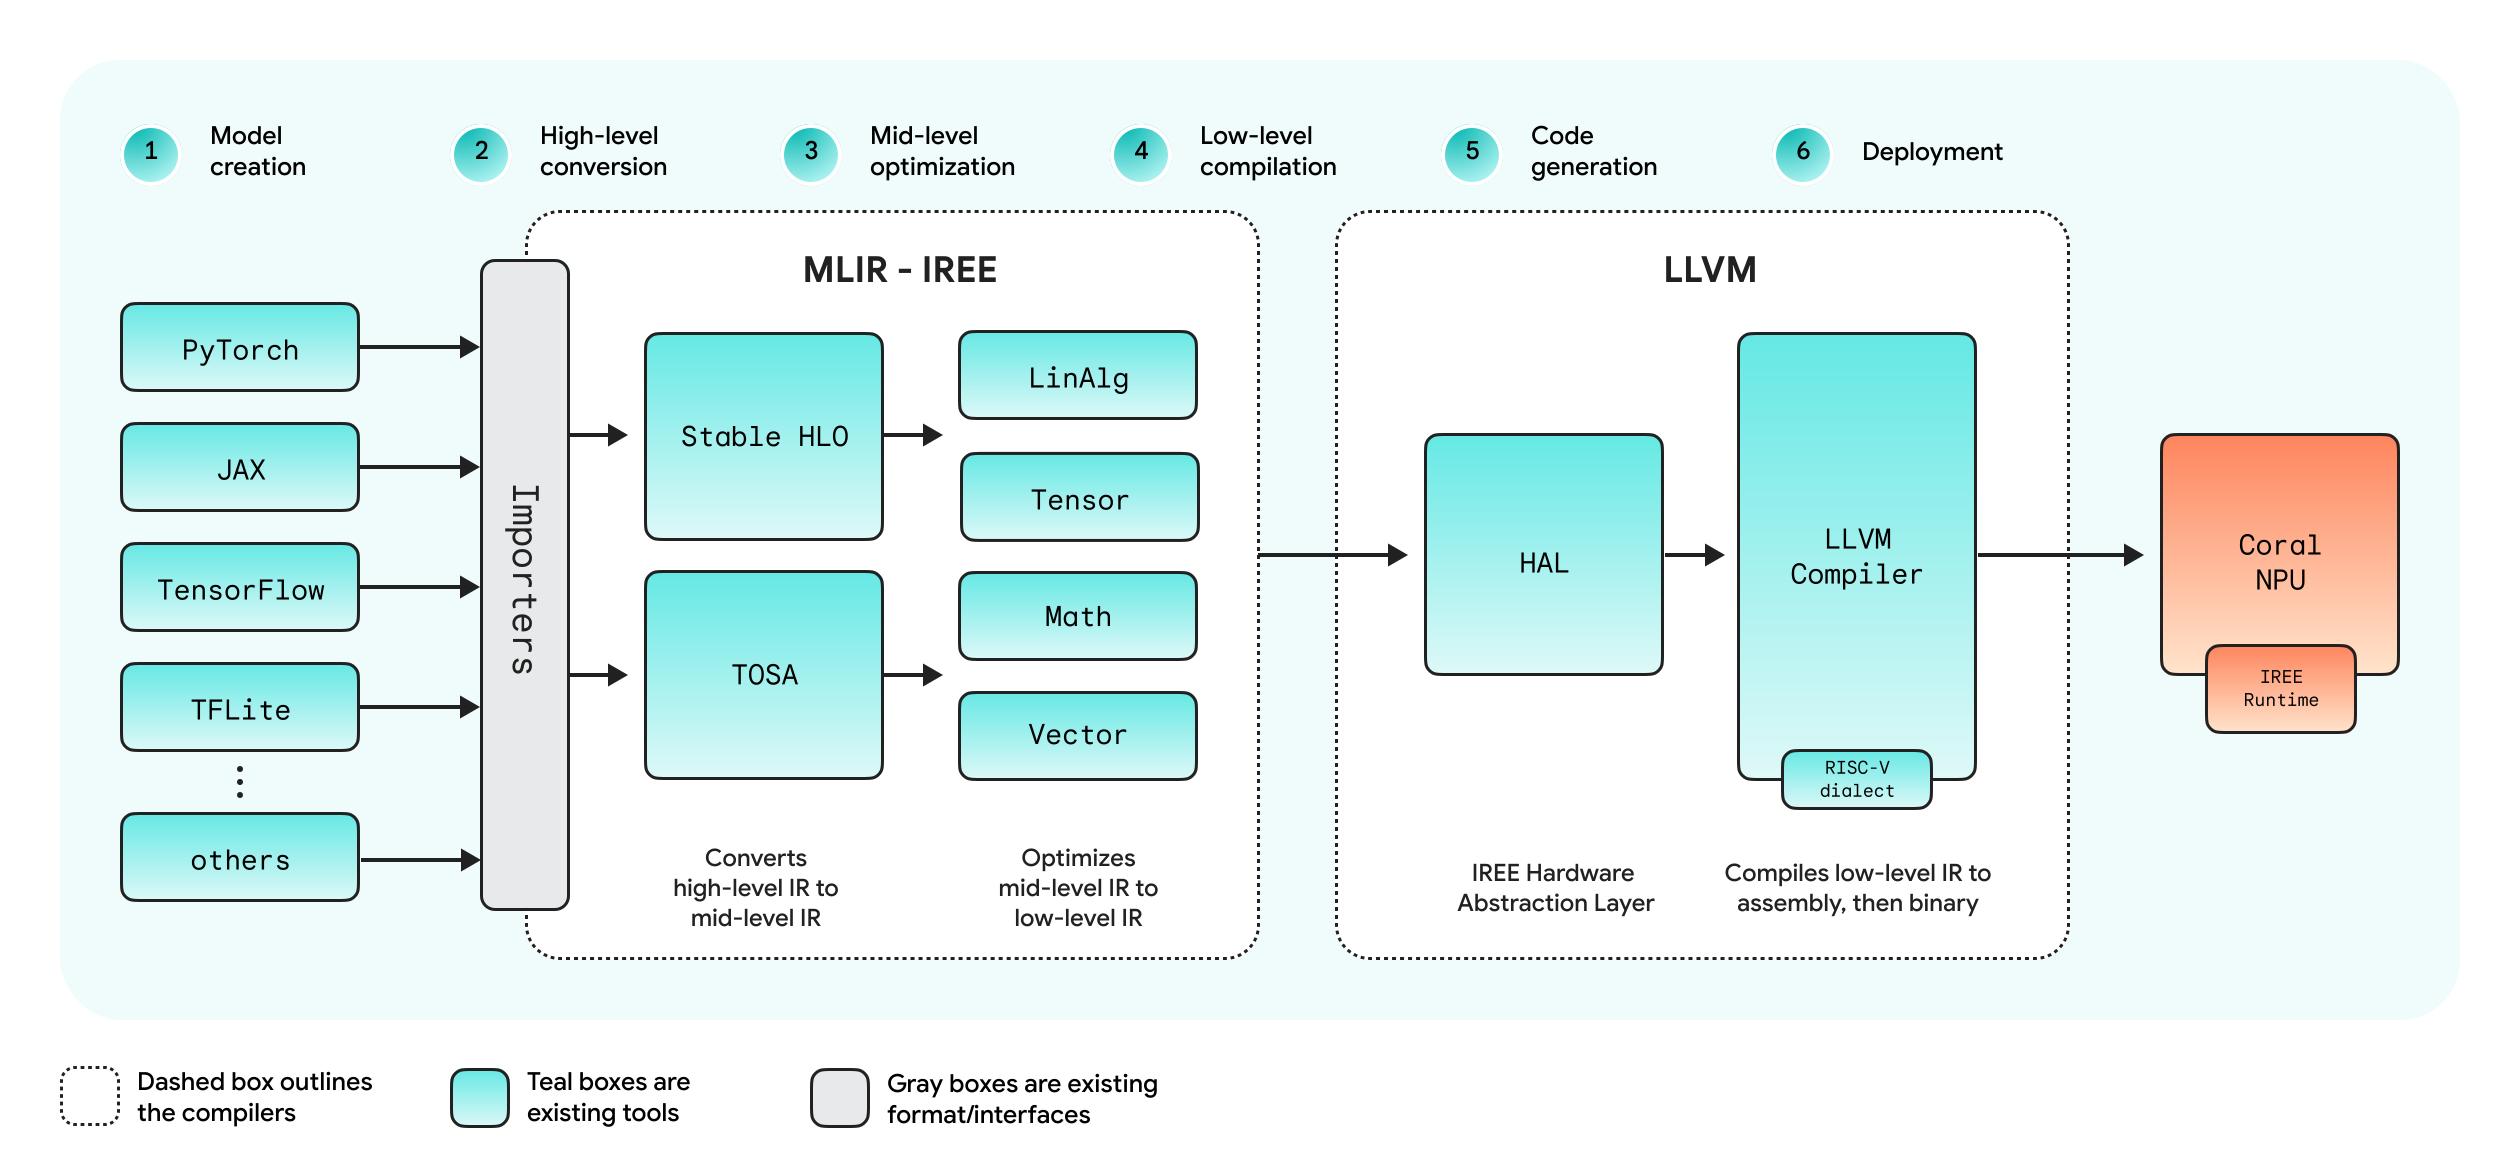
The overall workflow of an IREE-MLIR compiler is as follows:
- Convert your LiteRT (TensorFlow Lite), JAX, or PyTorch model to MLIR. For example, an IREE compiler may provide a command-line tool that converts a TensorFlow model to a binary MLIR file expressed in TOSA (Tensor Operator Set Architecture) dialect.
- For PyTorch models, convert to MLIR using the torch-mlir toolchain. This process involves exporting the PyTorch model and converting it to MLIR in various dialects such as TORCH, TOSA, LINALG_ON_TENSORS, or STABLEHLO.
- Input the resulting file to the IREE compiler.
- The input type tells the compiler what kind of intermediate representation (IR) it's processing, such as TOSA or PyTorch dialects, and selects the appropriate frontend pipeline.
- To execute your model, specify the input structure for the IREE run module
tool (
iree-run-module). You must match the expected shape, data type, and order of the model's inputs (model signature). Inputs can be provided directly as literals or loaded from files such as.npzor.bin.
Starting from Python code (LiteRT, for example), the compiler converts it to a LiteRT (TFLite) buffer which is then transformed into a TOSA file (the MLIR dialect); finally, the result is compiled into a binary for the target device. More details on the IREE TFLite tools can be found on the IREE site.
The guiding principle of MLIR is to have explicit lowering stages in the compilation, where each stage (dialect) represents a more concrete program representation. This allows for appropriate optimizations at each level.
Key concepts for MLIR
- Preserving high-level domain context: Traditional compilers rely on a fixed, very low-level set of instructions. When compilation tools process high-level structures — such as machine learning graphs, dataflow structures, or multidimensional arrays – they throw away helpful architectural context too early, forcing compiler developers to repeatedly reinvent complex optimizations.
- Multi-level representation: MLIR allows code to be analyzed and optimized at various semantic levels, from high-level neural network graphs down to low-level hardware memory layouts, all within the same file.
- Progressive lowering: Instead of compiling high-level source code directly to assembly instructions in one massive step, MLIR gradually steps code down through multiple mid-level checkpoints (called progressive lowering) before sending it to a hardware target such as Coral NPU.
MLIR architecture components
- Dialects: Self-contained, custom ecosystems within MLIR that define their own operations, types, and attributes (for example tensor, linalg, gpu, arith).
- Operations (ops): The foundational units of execution. They can represent anything from an abstract 3D convolutional matrix down to a primitive hardware addition.
- Regions & blocks: Nested hierarchies that natively allow MLIR to understand complex loops, parallel execution trees, and structured control flows.
Synaptics Torq™ NPU compiler
The SL2610 processor family by Synaptics is the first commercially available SoC that includes the Coral NPU core. Synaptics' NPU IREE plugin enables the compilation of ML models for this SoC.
In particular, the Torq™ NPU compiler is customized to take advantage of the SL2610's matrix processing unit — which uses a custom instruction set. Note that this matrix engine is Synaptics-proprietary and is different from the Coral NPU matrix unit. For complete information, see the Torq compiler documentation and Synaptics' developer site.