The MediaPipe Image Classifier task lets you perform classification on images. You can use
this task to identify what an image represents among a set of categories defined
at training time. This task operates on image data with a machine learning (ML)
model as static data or a continuous stream and outputs a list of potential
categories ranked by descending probability score.
[Open in Web Demos](https://google-ai-edge.github.io/mediapipe-samples-web/#/vision/image_classifier)[Edit in StackBlitz](https://stackblitz.com/github/google-ai-edge/mediapipe-samples-web?file=src/tasks/image-classifier.ts)
## Quickstart
Install the SDK for your platform,
[prepare input data](https://developers.google.com/edge/mediapipe/solutions/prepare_data.md.txt#vision), choose a
running mode, and run inference.
### Web
npm`npm install @mediapipe/tasks-vision`[Web demo](https://google-ai-edge.github.io/mediapipe-samples-web/#/vision/image_classifier)·[Edit in StackBlitz](https://stackblitz.com/github/google-ai-edge/mediapipe-samples-web?file=src/tasks/image-classifier.ts)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_web.md.txt)
#### Image
`IMAGE`Stateless · single frameSynchronous call on independent still images. Resets temporal tracking state on every call.
```typescript
import { FilesetResolver, ImageClassifier } from "@mediapipe/tasks-vision";
const vision = await FilesetResolver.forVisionTasks(
"https://cdn.jsdelivr.net/npm/@mediapipe/tasks-vision@latest/wasm"
);
const imageClassifier = await ImageClassifier.createFromOptions(vision, {
baseOptions: { modelAssetPath: "efficientnet_lite0.tflite", delegate: "GPU" },
runningMode: "IMAGE",
maxResults: 5,
});
// Synchronous single-frame call (stateless across images)
const image = document.getElementById("image") as HTMLImageElement;
const result = imageClassifier.classify(image);
```
#### Video
`VIDEO`Every frame · no dropsSynchronous tracking across decoded video frames with monotonic timestamps. Processes every frame in order and never drops frames.
```typescript
import { FilesetResolver, ImageClassifier } from "@mediapipe/tasks-vision";
const vision = await FilesetResolver.forVisionTasks(
"https://cdn.jsdelivr.net/npm/@mediapipe/tasks-vision@latest/wasm"
);
const imageClassifier = await ImageClassifier.createFromOptions(vision, {
baseOptions: { modelAssetPath: "efficientnet_lite0.tflite", delegate: "GPU" },
runningMode: "VIDEO",
maxResults: 5,
});
// Synchronous across decoded frames with monotonic timestamps (never drops frames)
for (const { frame, timestampMs } of decodedVideoFrames) {
const result = imageClassifier.classifyForVideo(frame, timestampMs);
}
```
#### Livestream
`VIDEO + rAF`Live camera · latest frameWeb tasks run synchronously---pair `runningMode: "VIDEO"` with `requestAnimationFrame` so each paint inspects only the latest camera frame (skipping intermediate frames when busy).
```typescript
import { FilesetResolver, ImageClassifier } from "@mediapipe/tasks-vision";
const vision = await FilesetResolver.forVisionTasks(
"https://cdn.jsdelivr.net/npm/@mediapipe/tasks-vision@latest/wasm"
);
// On Web, live camera loops pair runningMode: "VIDEO" with requestAnimationFrame
const imageClassifier = await ImageClassifier.createFromOptions(vision, {
baseOptions: { modelAssetPath: "efficientnet_lite0.tflite", delegate: "GPU" },
runningMode: "VIDEO",
maxResults: 5,
});
const video = document.getElementById("webcam") as HTMLVideoElement;
video.srcObject = await navigator.mediaDevices.getUserMedia({ video: true });
await video.play();
let lastVideoTime = -1;
function renderLoop() {
if (video.readyState >= 2 && video.currentTime !== lastVideoTime) {
lastVideoTime = video.currentTime;
const result = imageClassifier.classifyForVideo(video, performance.now());
console.log(result.classifications);
}
requestAnimationFrame(renderLoop);
}
renderLoop();
```
### Android (Kotlin)
Gradle`implementation("com.google.mediapipe:tasks-vision:latest.release")`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/image_classification/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
#### Image
`IMAGE`Stateless · single frameSynchronous call on independent still images. Resets temporal tracking state on every call.
```kotlin
import com.google.mediapipe.framework.image.BitmapImageBuilder
import com.google.mediapipe.framework.image.MPImage
import com.google.mediapipe.tasks.core.BaseOptions
import com.google.mediapipe.tasks.vision.core.RunningMode
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier
val baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build()
val options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.IMAGE)
.setMaxResults(5)
.build()
val imageClassifier = ImageClassifier.createFromOptions(context, options)
// Synchronous single-image call (no temporal tracking across calls)
val mpImage = BitmapImageBuilder(bitmap).build()
val result = imageClassifier.classify(mpImage)
```
#### Video
`VIDEO`Every frame · no dropsSynchronous tracking across decoded video frames with monotonic timestamps. Processes every frame in order and never drops frames.
```kotlin
import com.google.mediapipe.framework.image.BitmapImageBuilder
import com.google.mediapipe.framework.image.MPImage
import com.google.mediapipe.tasks.core.BaseOptions
import com.google.mediapipe.tasks.vision.core.RunningMode
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier
val baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build()
val options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.VIDEO)
.setMaxResults(5)
.build()
val imageClassifier = ImageClassifier.createFromOptions(context, options)
// Synchronous: processes every frame in order with monotonic timestamps (no frame drops)
val mpImage = BitmapImageBuilder(frameBitmap).build()
val result = imageClassifier.classifyForVideo(mpImage, frameTimestampMs)
```
#### Livestream
`LIVE_STREAM`Async · drops frames when busyAsynchronous camera pipeline with a result callback. Automatically drops incoming frames when busy so results stay current with low latency.
```kotlin
import android.os.SystemClock
import android.util.Log
import com.google.mediapipe.framework.image.BitmapImageBuilder
import com.google.mediapipe.framework.image.MPImage
import com.google.mediapipe.tasks.core.BaseOptions
import com.google.mediapipe.tasks.vision.core.RunningMode
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier
val baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build()
val options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.LIVE_STREAM)
.setMaxResults(5)
.setResultListener { result, _ -> val categories = result.classificationResult().classifications() }
.setErrorListener { error -> Log.e("MediaPipe", error.message.orEmpty()) }
.build()
val imageClassifier = ImageClassifier.createFromOptions(context, options)
// Async: automatically drops incoming camera frames when busy so results stay current
imageClassifier.classifyAsync(mpImage, SystemClock.uptimeMillis())
```
### Android (Java)
Gradle`implementation 'com.google.mediapipe:tasks-vision:latest.release'`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/image_classification/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
#### Image
`IMAGE`Stateless · single frameSynchronous call on independent still images. Resets temporal tracking state on every call.
```java
import com.google.mediapipe.framework.image.BitmapImageBuilder;
import com.google.mediapipe.framework.image.MPImage;
import com.google.mediapipe.tasks.core.BaseOptions;
import com.google.mediapipe.tasks.vision.core.RunningMode;
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier;
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifierResult;
BaseOptions baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build();
ImageClassifier.ImageClassifierOptions options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.IMAGE)
.setMaxResults(5)
.build();
ImageClassifier imageClassifier = ImageClassifier.createFromOptions(context, options);
// Synchronous single-image call (no temporal tracking across calls)
MPImage mpImage = new BitmapImageBuilder(bitmap).build();
ImageClassifierResult result = imageClassifier.classify(mpImage);
```
#### Video
`VIDEO`Every frame · no dropsSynchronous tracking across decoded video frames with monotonic timestamps. Processes every frame in order and never drops frames.
```java
import com.google.mediapipe.framework.image.BitmapImageBuilder;
import com.google.mediapipe.framework.image.MPImage;
import com.google.mediapipe.tasks.core.BaseOptions;
import com.google.mediapipe.tasks.vision.core.RunningMode;
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier;
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifierResult;
BaseOptions baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build();
ImageClassifier.ImageClassifierOptions options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.VIDEO)
.setMaxResults(5)
.build();
ImageClassifier imageClassifier = ImageClassifier.createFromOptions(context, options);
// Synchronous: processes every frame in order with monotonic timestamps (no frame drops)
MPImage mpImage = new BitmapImageBuilder(frameBitmap).build();
ImageClassifierResult result = imageClassifier.classifyForVideo(mpImage, frameTimestampMs);
```
#### Livestream
`LIVE_STREAM`Async · drops frames when busyAsynchronous camera pipeline with a result callback. Automatically drops incoming frames when busy so results stay current with low latency.
```java
import android.os.SystemClock;
import android.util.Log;
import com.google.mediapipe.framework.image.BitmapImageBuilder;
import com.google.mediapipe.framework.image.MPImage;
import com.google.mediapipe.tasks.core.BaseOptions;
import com.google.mediapipe.tasks.vision.core.RunningMode;
import com.google.mediapipe.tasks.vision.imageclassifier.ImageClassifier;
BaseOptions baseOptions = BaseOptions.builder()
.setModelAssetPath("efficientnet_lite0.tflite")
.build();
ImageClassifier.ImageClassifierOptions options = ImageClassifier.ImageClassifierOptions.builder()
.setBaseOptions(baseOptions)
.setRunningMode(RunningMode.LIVE_STREAM)
.setMaxResults(5)
.setResultListener((result, inputImage) -> { var categories = result.classificationResult().classifications(); })
.setErrorListener(error -> Log.e("MediaPipe", String.valueOf(error.getMessage())))
.build();
ImageClassifier imageClassifier = ImageClassifier.createFromOptions(context, options);
// Async: automatically drops incoming camera frames when busy so results stay current
imageClassifier.classifyAsync(mpImage, SystemClock.uptimeMillis());
```
### iOS
SwiftPM`https://github.com/google-ai-edge/mediapipe → MediaPipeTasksVision`[Package.swift](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt#package_swift)·[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/image_classification/ios)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt)
#### Image
`IMAGE`Stateless · single frameSynchronous call on independent still images. Resets temporal tracking state on every call.
```swift
import Foundation
import MediaPipeTasksVision
guard let modelPath = Bundle.main.path(forResource: "efficientnet_lite0", ofType: "tflite") else { return }
let options = ImageClassifierOptions()
options.baseOptions.modelAssetPath = modelPath
options.runningMode = .image
options.maxResults = 5
let imageClassifier = try ImageClassifier(options: options)
// Synchronous single-image call (stateless across images)
let mpImage = try MPImage(uiImage: image)
let result = try imageClassifier.classify(image: mpImage)
```
#### Video
`VIDEO`Every frame · no dropsSynchronous tracking across decoded video frames with monotonic timestamps. Processes every frame in order and never drops frames.
```swift
import Foundation
import MediaPipeTasksVision
guard let modelPath = Bundle.main.path(forResource: "efficientnet_lite0", ofType: "tflite") else { return }
let options = ImageClassifierOptions()
options.baseOptions.modelAssetPath = modelPath
options.runningMode = .video
options.maxResults = 5
let imageClassifier = try ImageClassifier(options: options)
// Synchronous: processes every frame in order with monotonic timestamps (no frame drops)
let mpImage = try MPImage(pixelBuffer: pixelBuffer)
let result = try imageClassifier.classify(videoFrame: mpImage, timestampInMilliseconds: timestampMs)
```
#### Livestream
`LIVE_STREAM`Async · drops frames when busyAsynchronous camera pipeline with a result callback. Automatically drops incoming frames when busy so results stay current with low latency.
```swift
import Foundation
import MediaPipeTasksVision
final class ImageClassifierStreamService: NSObject {
private var imageClassifier: ImageClassifier?
func setUp() throws {
guard let modelPath = Bundle.main.path(
forResource: "efficientnet_lite0",
ofType: "tflite"
) else { return }
let options = ImageClassifierOptions()
options.baseOptions.modelAssetPath = modelPath
options.runningMode = .liveStream
options.maxResults = 5
options.imageClassifierLiveStreamDelegate = self
imageClassifier = try ImageClassifier(options: options)
}
func classifyAsync(mpImage: MPImage, timestampMs: Int) throws {
// Async: automatically drops incoming camera frames when busy so results stay current
try imageClassifier?.classifyAsync(image: mpImage, timestampInMilliseconds: timestampMs)
}
}
extension ImageClassifierStreamService: ImageClassifierLiveStreamDelegate {
func imageClassifier(
_ imageClassifier: ImageClassifier,
didFinishClassification result: ImageClassifierResult?,
timestampInMilliseconds: Int,
error: (any Error)?
) {
guard let result else { return }
DispatchQueue.main.async {
let categories = result.classificationResult.classifications
}
}
}
```
### Python
pip`pip install mediapipe`[Sample code](https://colab.research.google.com/github/google-ai-edge/mediapipe-samples/blob/main/examples/image_classification/python/image_classifier.ipynb)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_python.md.txt)
#### Image
`IMAGE`Stateless · single frameSynchronous call on independent still images. Resets temporal tracking state on every call.
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
ImageClassifier = mp.tasks.vision.ImageClassifier
ImageClassifierOptions = mp.tasks.vision.ImageClassifierOptions
VisionRunningMode = mp.tasks.vision.RunningMode
options = ImageClassifierOptions(
base_options=BaseOptions(model_asset_path="efficientnet_lite0.tflite"),
running_mode=VisionRunningMode.IMAGE,
max_results=5,
)
with ImageClassifier.create_from_options(options) as classifier:
# Synchronous single-image call (stateless across images)
mp_image = mp.Image.create_from_file("input.jpg")
result = classifier.classify(mp_image)
```
#### Video
`VIDEO`Every frame · no dropsSynchronous tracking across decoded video frames with monotonic timestamps. Processes every frame in order and never drops frames.
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
ImageClassifier = mp.tasks.vision.ImageClassifier
ImageClassifierOptions = mp.tasks.vision.ImageClassifierOptions
VisionRunningMode = mp.tasks.vision.RunningMode
options = ImageClassifierOptions(
base_options=BaseOptions(model_asset_path="efficientnet_lite0.tflite"),
running_mode=VisionRunningMode.VIDEO,
max_results=5,
)
with ImageClassifier.create_from_options(options) as classifier:
# Synchronous: processes every frame in order with monotonic timestamps (no frame drops)
for mp_image, timestamp_ms in decoded_video_frames:
result = classifier.classify_for_video(mp_image, timestamp_ms)
```
#### Livestream
`LIVE_STREAM`Async · drops frames when busyAsynchronous camera pipeline with a result callback. Automatically drops incoming frames when busy so results stay current with low latency.
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
ImageClassifier = mp.tasks.vision.ImageClassifier
ImageClassifierOptions = mp.tasks.vision.ImageClassifierOptions
VisionRunningMode = mp.tasks.vision.RunningMode
def on_result(result, output_image: mp.Image, timestamp_ms: int):
print(f"Classifications at {timestamp_ms} ms: {result.classifications}")
options = ImageClassifierOptions(
base_options=BaseOptions(model_asset_path="efficientnet_lite0.tflite"),
running_mode=VisionRunningMode.LIVE_STREAM,
max_results=5,
result_callback=on_result,
)
with ImageClassifier.create_from_options(options) as classifier:
# Async: automatically drops incoming camera frames when busy so results stay current
mp_image = mp.Image(image_format=mp.ImageFormat.SRGB, data=rgb_frame)
classifier.classify_async(mp_image, timestamp_ms)
```
### Flutter
pub`flutter pub add mediapipe_vision`[Live gallery](https://google.github.io/flutter-mediapipe/)·[Sample code](https://github.com/google/flutter-mediapipe/tree/main/samples/vision/image_classifier)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_flutter.md.txt)
#### Image
`RunningMode.image`Stateless · single frameOne call per independent still image. No tracking state carries over between calls.
```dart
import 'package:mediapipe_vision/mediapipe_vision.dart';
Future classifyPhoto(VisionImage image) async {
final classifier = await ImageClassifier.create(
ImageClassifierOptions(model: VisionModels.imageClassifier, maxResults: 3),
);
try {
final result = await classifier.classify(image);
for (final category in result.classifications.first.categories) {
print('${category.categoryName}: ${category.score.toStringAsFixed(2)}');
}
} finally {
await classifier.dispose();
}
}
```
#### Video
`RunningMode.video`Every frame · no dropsTracking across decoded video frames with strictly increasing timestamps. Processes every frame in order and never drops frames.
```dart
import 'dart:typed_data';
import 'package:mediapipe_vision/mediapipe_vision.dart';
typedef Frame = ({Uint8List rgba, int width, int height, int milliseconds});
Future classifyFramesInVideo(Stream frames) async {
final classifier = await ImageClassifier.create(
ImageClassifierOptions(
model: VisionModels.imageClassifier,
runningMode: RunningMode.video,
maxResults: 3,
),
);
try {
await for (final frame in frames) {
final result = await classifier.classifyForVideo(
VisionImage.fromPixels(
pixels: frame.rgba,
width: frame.width,
height: frame.height,
format: VisionPixelFormat.rgba,
),
timestampMilliseconds: frame.milliseconds,
);
final ms = result.timestampMilliseconds;
final top = result.classifications.first.categories.map(
(category) =>
'${category.categoryName} ${category.score.toStringAsFixed(2)}',
);
print('$ms ms: ${top.join(', ')}');
}
} finally {
await classifier.dispose();
}
}
```
#### Livestream
`RunningMode.liveStream`Async · drops frames when busyEach call returns at once and results arrive on the task's `results` stream. One frame runs at a time; a newer frame replaces one that's waiting, so results stay current.
```dart
import 'dart:typed_data';
import 'package:mediapipe_vision/mediapipe_vision.dart';
typedef Frame = ({Uint8List rgba, int width, int height, int milliseconds});
Future classifyFramesLive(Stream frames) async {
final classifier = await ImageClassifier.create(
ImageClassifierOptions(
model: VisionModels.imageClassifier,
runningMode: RunningMode.liveStream,
maxResults: 3,
),
);
// Listen before the first frame, as Google requires a result listener.
final results = classifier.results.listen((result) {
final ms = result.timestampMilliseconds;
final top = result.classifications.first.categories.map(
(category) =>
'${category.categoryName} ${category.score.toStringAsFixed(2)}',
);
print('$ms ms: ${top.join(', ')}');
});
try {
await for (final frame in frames) {
classifier.classifyAsync(
VisionImage.fromPixels(
pixels: frame.rgba,
width: frame.width,
height: frame.height,
format: VisionPixelFormat.rgba,
),
timestampMilliseconds: frame.milliseconds,
);
}
} finally {
// Runs the frame in flight and the waiting one, then closes results.
await classifier.dispose();
await results.cancel();
print('${classifier.droppedFrames} frames dropped');
}
}
```
## Task details
This section describes the capabilities, inputs, outputs, and configuration
options of this task.
### Features
- **Input image processing** - Processing includes image rotation, resizing, normalization, and color space conversion.
- **Region of interest** - Perform classification on a region of the image instead of the whole image.
- **Label map locale** - Set the language used for display names.
- **Score threshold** - Filter results based on prediction scores.
- **Top-k classification** - Limit the number of classification results.
- **Label allowlist and denylist** - Specify the categories classified.
Inputs The Image Classifier accepts an input of one of the following data types:
- Still images
- Decoded video frames
- Live video feed
See [Prepare vision input data](https://developers.google.com/edge/mediapipe/solutions/prepare_data.md.txt#vision) for `MPImage`, `mp.Image`, `VisionImage`, and browser media examples.
Outputs Image Classifier outputs a list of categories containing:
- Category index: the index of the category in the model outputs
- Score: the confidence score for this category, usually a probability in \[0,1\]
- Category name (optional): the name of the category as specified in the LiteRT model metadata, if available
- Category display name (optional): a display name for the category as specified in the LiteRT model metadata, in the language specified through display names locale options, if available
### Configuration options
This task has the following configuration options:
### Web
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `runningMode` | Sets the running mode for the task: `IMAGE`: Single image inputs. `VIDEO`: Decoded video frames and live camera streams. | {`IMAGE`, `VIDEO`} | `IMAGE` |
| `displayNamesLocale` | Locale code for display names provided in the model metadata, if available. You can add localized labels to custom models with the [LiteRT Metadata Writer API](https://developers.google.com/edge/litert/conversion/tensorflow/metadata_writer_tutorial.md.txt). | Locale code | `"en"` |
| `maxResults` | Maximum number of top-scored classification results to return (`-1` returns all results). | Integer | `-1` |
| `scoreThreshold` | Prediction score threshold overriding the model metadata default. Classifications lower than this score are rejected. | Float `[0.0, 1.0]` | Not set |
| `categoryAllowlist` | Optional list of allowed category names. Mutually exclusive with `categoryDenylist`. | List of strings | Not set |
| `categoryDenylist` | Optional list of excluded category names. Mutually exclusive with `categoryAllowlist`. | List of strings | Not set |
### Android
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `runningMode` | Sets the running mode for the task: `IMAGE`: Single image inputs. `VIDEO`: Decoded frames of a video. `LIVE_STREAM`: Livestream of camera input data (requires asynchronous listener/delegate). | {`IMAGE`, `VIDEO`, `LIVE_STREAM`} | `IMAGE` |
| `displayNamesLocale` | Locale code for display names provided in the model metadata, if available. You can add localized labels to custom models with the [LiteRT Metadata Writer API](https://developers.google.com/edge/litert/conversion/tensorflow/metadata_writer_tutorial.md.txt). | Locale code | `"en"` |
| `maxResults` | Maximum number of top-scored classification results to return (`-1` returns all results). | Integer | `-1` |
| `scoreThreshold` | Prediction score threshold overriding the model metadata default. Classifications lower than this score are rejected. | Float `[0.0, 1.0]` | Not set |
| `categoryAllowlist` | Optional list of allowed category names. Mutually exclusive with `categoryDenylist`. | List of strings | Not set |
| `categoryDenylist` | Optional list of excluded category names. Mutually exclusive with `categoryAllowlist`. | List of strings | Not set |
| `resultListener` | Asynchronous callback for `LIVE_STREAM` mode results. | `OutputHandler.ResultListener` | Not set |
| `errorListener` | Optional error listener for `LIVE_STREAM` mode. | `ErrorListener` | Not set |
### iOS
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `runningMode` | Sets the running mode for the task: `IMAGE`: Single image inputs. `VIDEO`: Decoded frames of a video. `LIVE_STREAM`: Livestream of camera input data (requires asynchronous listener/delegate). | {`IMAGE`, `VIDEO`, `LIVE_STREAM`} | `IMAGE` |
| `displayNamesLocale` | Locale code for display names provided in the model metadata, if available. You can add localized labels to custom models with the [LiteRT Metadata Writer API](https://developers.google.com/edge/litert/conversion/tensorflow/metadata_writer_tutorial.md.txt). | Locale code | `"en"` |
| `maxResults` | Maximum number of top-scored classification results to return (`-1` returns all results). | Integer | `-1` |
| `scoreThreshold` | Prediction score threshold overriding the model metadata default. Classifications lower than this score are rejected. | Float `[0.0, 1.0]` | Not set |
| `categoryAllowlist` | Optional list of allowed category names. Mutually exclusive with `categoryDenylist`. | List of strings | Not set |
| `categoryDenylist` | Optional list of excluded category names. Mutually exclusive with `categoryAllowlist`. | List of strings | Not set |
| `imageClassifierLiveStreamDelegate` | Asynchronous delegate for `LIVE_STREAM` mode results (invoked on a serial background queue). | `ImageClassifierLiveStreamDelegate` | Not set |
### Python
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `running_mode` | Sets the running mode for the task: `IMAGE`: Single image inputs. `VIDEO`: Decoded frames of a video. `LIVE_STREAM`: Livestream of camera input data (requires `result_callback`). | {`IMAGE`, `VIDEO`, `LIVE_STREAM`} | `IMAGE` |
| `display_names_locale` | Locale code for display names provided in the model metadata, if available. You can add localized labels to custom models with the [LiteRT Metadata Writer API](https://developers.google.com/edge/litert/conversion/tensorflow/metadata_writer_tutorial.md.txt). | Locale code | `"en"` |
| `max_results` | Maximum number of top-scored classification results to return (`-1` returns all results). | Integer | `-1` |
| `score_threshold` | Prediction score threshold overriding the model metadata default. Classifications lower than this score are rejected. | Float `[0.0, 1.0]` | Not set |
| `category_allowlist` | Optional list of allowed category names. Mutually exclusive with `category_denylist`. | List of strings | Not set |
| `category_denylist` | Optional list of excluded category names. Mutually exclusive with `category_allowlist`. | List of strings | Not set |
| `result_callback` | Asynchronous callback function for `LIVE_STREAM` mode results. | `Callable` | Not set |
### Flutter
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `runningMode` | Sets the running mode for the task: `RunningMode.image`: Single image inputs. `RunningMode.video`: Decoded frames of a video. `RunningMode.liveStream`: Livestream of camera input data (results arrive on the task's `results` stream). | {`RunningMode.image`, `RunningMode.video`, `RunningMode.liveStream`} | `RunningMode.image` |
| `displayNamesLocale` | Locale code for display names provided in the model metadata, if available. You can add localized labels to custom models with the [LiteRT Metadata Writer API](https://developers.google.com/edge/litert/conversion/tensorflow/metadata_writer_tutorial.md.txt). When `null`, Google's default applies. | Locale code | `null` |
| `maxResults` | Maximum number of top-scored classification results to return per head (a negative value returns all results; `0` is rejected). | Integer | `-1` |
| `scoreThreshold` | Prediction score threshold. Classifications lower than this score are rejected. | Float `[0.0, 1.0]` | `0` |
| `categoryAllowlist` | Optional list of allowed category names. Mutually exclusive with `categoryDenylist`. | `List` | Empty |
| `categoryDenylist` | Optional list of excluded category names. Mutually exclusive with `categoryAllowlist`. | `List` | Empty |
### Task output
Each `ImageClassifierResult` contains one `Classifications` entry per classification head:
| Field | Type / Range | Description |
|---|---|---|
| `classifications` | `Classifications[]` | Per-head classification results (`headIndex`, `headName`, `categories`). |
| `categories` | `Category[]` (`score` in `[0.0, 1.0]`) | Ranked predicted classes (`categoryName`, `displayName`, `index`, `score`; in Dart, a `List`, named to avoid Flutter's own `Category`). |
#### Example `ImageClassifierResult` payload
The following example shows the top predicted classes from a single classification head:
```javascript
{
classifications: [
{
headIndex: 0,
categories: [
{ index: 671, score: 0.9141, categoryName: "/m/01bwb9", displayName: "Passer domesticus" },
{ index: 670, score: 0.0039, categoryName: "/m/01bwbt", displayName: "Passer montanus" }
]
}
]
}
```
> [!NOTE]
> **Note:** The category allowlist and denylist are mutually exclusive.
## Models
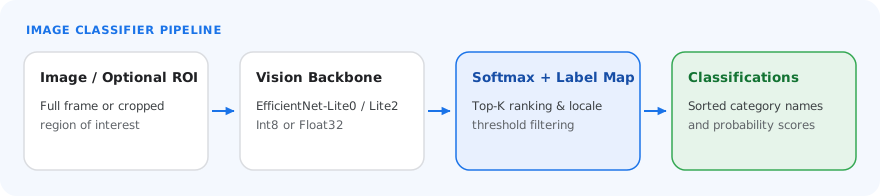
The Image Classifier requires an image classification model to be downloaded and
stored in your project directory. Start with the default, recommended model for
your target platform when you start developing with this task. The other
available models typically make trade-offs between performance, accuracy,
resolution, and resource requirements, and in some cases, include additional
features.
### EfficientNet-Lite0 model (recommended)
The EfficientNet-Lite0 model uses an EfficientNet architecture and was trained
using [ImageNet](https://www.image-net.org) to recognize 1,000 classes, such as
trees, animals, food, vehicles, and people. See the [full
list](https://storage.googleapis.com/mediapipe-tasks/image_classifier/labels.txt)
of supported labels. EfficientNet-Lite0 is available as an int8 and float 32
model. This model is recommended because it strikes a balance between latency
and accuracy. It is both accurate and lightweight enough for many use cases.
| Model name | Input shape | Quantization type | Versions |
|---|---|---|---|
| [EfficientNet-Lite0 (int8)](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite0/int8/latest/efficientnet_lite0.tflite) | 224 x 224 | int8 | [Latest](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite0/int8/latest/efficientnet_lite0.tflite) |
| [EfficientNet-Lite0 (float 32)](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite0/float32/latest/efficientnet_lite0.tflite) | 224 x 224 | None (float32) | [Latest](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite0/float32/latest/efficientnet_lite0.tflite) |
### EfficientNet-Lite2 model
The EfficientNet-Lite2 model uses an EfficientNet architecture and was trained
using [ImageNet](https://www.image-net.org) to recognize 1,000 classes, such as
trees, animals, food, vehicles, and people. See the [full
list](https://storage.googleapis.com/mediapipe-tasks/image_classifier/labels.txt)
of supported labels. EfficientNet-Lite2 is available as an int8 and float 32
model. This model is generally more accurate than EfficientNet-Lite0, but is
also slower and more memory intensive. This model is appropriate for use cases
where accuracy is a higher priority than speed or size.
| Model name | Input shape | Quantization type | Versions |
|---|---|---|---|
| [EfficientNet-Lite2 (int8)](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite2/int8/latest/efficientnet_lite2.tflite) | 224 x 224 | int8 | [Latest](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite2/int8/latest/efficientnet_lite2.tflite) |
| [EfficientNet-Lite2 (float 32)](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite2/float32/latest/efficientnet_lite2.tflite) | 224 x 224 | None (float32) | [Latest](https://storage.googleapis.com/mediapipe-models/image_classifier/efficientnet_lite2/float32/latest/efficientnet_lite2.tflite) |
## Task benchmarks
Here are the task benchmarks for the whole pipeline based on the preceding pre-trained
models. The latency result is the average latency on Pixel 6 using CPU / GPU.
| Model name | Device | CPU latency | GPU latency |
|---|---|---|---|
| EfficientNet-Lite0 (float 32) | Pixel 6 | 23.52ms | 18.90ms |
| EfficientNet-Lite0 (int8) | Pixel 6 | 10.08ms | - |
| EfficientNet-Lite2 (float 32) | Pixel 6 | 44.17ms | 22.20ms |
| EfficientNet-Lite2 (int8) | Pixel 6 | 19.43ms | - |