The MediaPipe Text Proofreader task lets you identify spelling, grammatical, and stylistic
errors in a text and generate a corrected version while maintaining the original
meaning. This task operates on text data with a machine learning (ML) model and
outputs the corrected text.
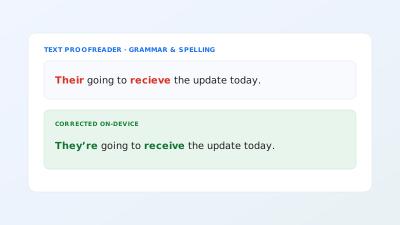 On-device demo Text Proofreader Detect and correct grammar, spelling, and style errors locally with Gemma 3 1B. Available on Android, iOS, and desktop Python with on-device Gemma 3 1B via LiteRT-LM. On-device benchmark · Pixel 10 Pro CPU Gemma 3 1B · 100 words Prefill1,280tok/sDecode170tok/sE2E980ms
## Quickstart
Install the SDK for your platform, initialize the task with a model, and run
inference.
### Android (Kotlin)
Gradle`implementation("com.google.mediapipe:tasks-text:latest.release")`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/text_proofreader/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
```kotlin
import com.google.mediapipe.tasks.text.textproofreader.TextProofreader
import com.google.mediapipe.tasks.text.textproofreader.TextProofreader.TextProofreaderOptions
val options = TextProofreaderOptions.builder()
.setModelPath("${context.filesDir}/proofread_quant_200m.litertlm")
.build()
val proofreader = TextProofreader.createFromOptions(context, options)
val inputText = "Their are severel typos in this sentance."
val result = proofreader.proofread(inputText)
val correctedText = result.proofreadText
```
### Android (Java)
Gradle`implementation 'com.google.mediapipe:tasks-text:latest.release'`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/text_proofreader/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
```java
import com.google.mediapipe.tasks.text.textproofreader.TextProofreader;
import com.google.mediapipe.tasks.text.textproofreader.TextProofreader.TextProofreaderOptions;
import com.google.mediapipe.tasks.text.textproofreader.TextProofreaderResult;
TextProofreaderOptions options = TextProofreaderOptions.builder()
.setModelPath(context.getFilesDir() + "/proofread_quant_200m.litertlm")
.build();
TextProofreader proofreader = TextProofreader.createFromOptions(context, options);
String inputText = "Their are severel typos in this sentance.";
TextProofreaderResult result = proofreader.proofread(inputText);
String correctedText = result.getProofreadText();
```
### iOS
SwiftPM`https://github.com/google-ai-edge/mediapipe → MediaPipeTasksText`[Package.swift](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt#package_swift)·[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/text_proofreader/ios)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt)
```swift
import Foundation
import MediaPipeTasksText
guard let modelPath = Bundle.main.path(forResource: "proofread_quant_200m", ofType: "litertlm") else { return }
let options = TextProofreaderOptions()
options.baseOptions.modelAssetPath = modelPath
let textProofreader = try TextProofreader(options: options)
let inputText = "Their are severel typos in this sentance."
let result = try textProofreader.proofread(text: inputText)
let correctedText = result.proofreadText
```
### Python
pip`pip install mediapipe`[Sample code](https://colab.research.google.com/github/google-ai-edge/mediapipe-samples/blob/main/examples/text_proofreader/python/text_proofreader.ipynb)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_python.md.txt)
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
TextProofreader = mp.tasks.text.TextProofreader
TextProofreaderOptions = mp.tasks.text.TextProofreaderOptions
model_path = "proofread_quant_200m.litertlm"
options = TextProofreaderOptions(base_options=BaseOptions(model_asset_path=model_path), max_num_tokens=4096)
input_text = "Their are severel typos in this sentance."
with TextProofreader.create_from_options(options) as text_proofreader:
result = text_proofreader.proofread(input_text)
corrected_text = result.proofread_text
```
### Flutter
pub`flutter pub add mediapipe_text`[Live gallery](https://google.github.io/flutter-mediapipe/)·[Sample code](https://github.com/google/flutter-mediapipe/tree/main/samples/text/text_proofreader)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_flutter.md.txt)
Text Proofreader isn't available in Flutter web apps yet.
```dart
import 'package:mediapipe_text/mediapipe_text.dart';
Future proofread() async {
final task = await TextProofreader.create(
TextProofreaderOptions(model: TextModels.proofreader),
);
try {
final result = await task.proofread('She go home.');
print(result.proofreadText);
for (final edit in result.corrections) {
print('${edit.type.name}: ${edit.text}');
}
await for (final update in task.proofreadStream(
'I recieved your mesage.',
)) {
if (update.chunk != null) print(update.chunk);
if (update.done) print(update.corrections);
}
} finally {
await task.dispose();
}
}
```
## Task details
This section describes the capabilities, inputs, outputs, and configuration
options of this task.
### Features
- **Input text processing** - Handles text pre-processing, including tokenization if needed.
- **Granular corrections** - Provides a detailed breakdown of granular corrections, allowing you to identify which words were inserted, deleted, or left unchanged.
Inputs Text Proofreader accepts the following input data type:
- String
Outputs The Text Proofreader outputs the following results:
- String: represents the proofread result.
- List of corrections: detailed breakdown of granular edits (insertions, deletions, or unchanged text segments).
### Configuration options
This task has the following configuration options:
### Android
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `modelPath` | Path to the `.litertlm` model file in device storage (or use `modelAssetFileDescriptor`). | `String` | Required |
| `maxNumTokens` | Optional limit on the maximum context length in tokens. If unset or `0`, defaults to the model's built-in capacity (`8192` tokens). | `Integer` | `0` (model default 8k) |
### iOS
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `baseOptions.modelAssetPath` | Path or URL to the proofreader model (`modelPath` or `modelAssetFileDescriptor` on Android). | `String` | Required |
| `maxNumTokens` | Optional limit on the maximum context length in tokens. If unset or `0`, defaults to the model's built-in capacity (`8192` tokens). | `Integer` | `0` (model default 8k) |
| `cacheDirectory` | Optional writable directory for the model weight and program caches. Pass `":nocache"` to disable caching. | `String` | Not set |
### Python
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `base_options.model_asset_path` | Path or URL to the proofreader model (`modelPath` or `modelAssetFileDescriptor` on Android). | `String` | Required |
| `max_num_tokens` | Optional limit on the maximum context length in tokens. If unset or `0`, defaults to the model's built-in capacity (`8192` tokens). | `Integer` | `0` (model default 8k) |
| `cache_dir` | Optional writable directory for the model weight and program caches. Pass `":nocache"` to disable caching. | `str` | `":nocache"` |
### Flutter
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `model` | Google's pinned proofreader model, `TextModels.proofreader`, bundled at build time (or `modelPath` to a `.litertlm` file on the device). Supply exactly one; `modelBytes` isn't accepted. | `DownloadAsset` | Required |
| `maxNumTokens` | Optional limit on the maximum context length in tokens, covering input and output. If `null` or `0`, defaults to the model's built-in capacity (`8192` tokens). | `int` `[0, 2147483647]` | `null` (model default 8k) |
| `cacheDirectory` | Optional writable directory where Google's runtime caches the prepared model. If `null`, Google's default (beside the model) is used. | `String` | `null` |
### Task output
Each `TextProofreaderResult` returns the corrected text together with a granular diff of word-level edits:
| Field | Type | Description |
|---|---|---|
| `proofreadText` | `string` | Complete proofread text with spelling, grammar, and stylistic corrections applied (`proofread_text` in Python; a nullable `String?` in Dart). |
| `corrections` | `Correction[]` | Ordered list of diff segments (`type`: `SAME`, `INSERTION`, or `DELETION`; `text`: `string`) comparing the original input to `proofreadText` (in Dart, `ProofreadingCorrection` with `type` as `ProofreadingCorrectionType.same`, `.insertion`, or `.deletion`). |
#### Example `TextProofreaderResult` payload
The following example shows the corrected string and granular edit segments returned for a sentence with typos:
```javascript
{
proofreadText: "There are several typos in this sentence.",
corrections: [
{ type: "DELETION", text: "Their" },
{ type: "INSERTION", text: "There" },
{ type: "SAME", text: " are " },
{ type: "DELETION", text: "severel" },
{ type: "INSERTION", text: "several" },
{ type: "SAME", text: " typos in this " },
{ type: "DELETION", text: "sentance." },
{ type: "INSERTION", text: "sentence." }
]
}
```
## Models
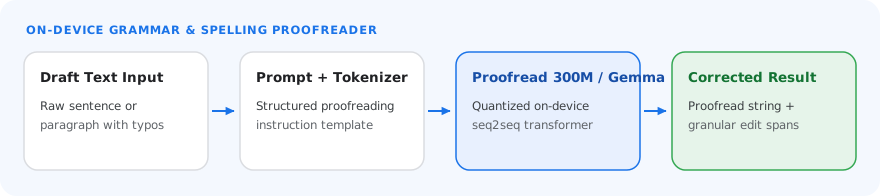
We offer a default, recommended model when you start developing with this task.
### Proofread 200M model (recommended)
A lightweight 200M parameter model fine-tuned to identify spelling, grammatical,
and stylistic errors in a text and generate a corrected version. This model is
subject to the [Gemma Terms of Use](https://ai.google.dev/gemma/terms).
| Model name | Input | Quantization type | Terms of use | Versions |
|---|---|---|---|---|
| [Text Proofreader](https://storage.googleapis.com/mediapipe-models/text_proofreader/200m/latest/proofread_quant_200m.litertlm) | string | Mixed Precision (Int4 + Int8) | [Gemma](https://ai.google.dev/gemma/terms) | [Latest](https://storage.googleapis.com/mediapipe-models/text_proofreader/200m/latest/proofread_quant_200m.litertlm) |
## Task benchmarks
Here are the task benchmarks for the whole pipeline on a Pixel 10 Pro CPU. Peak
memory usage for on-device model inference varies from approximately 200MB to
350MB depending on the input length (100 to 2000 words).
### MediaPipe E2E Benchmark
| Device | Input Words (tokens) | Prefill (tokens/s) | Decode (tokens/s) | E2E Latency (ms) |
|---|---|---|---|---|
| Pixel 10 Pro CPU | 100 (\~200 tokens) | 1280 | 170 | 980 |
| Pixel 10 Pro CPU | 500 (\~900 tokens) | 1095 | 163 | 4,900 |
| Pixel 10 Pro CPU | 1000 (\~1900 tokens) | 1025 | 150 | 16,000 |
| Pixel 10 Pro CPU | 2000 (\~3600 tokens) | 980 | 140 | 28,000 |